一部手机加入了 122B 推理
一台 Galaxy S25 从 hub 自主下载了自己的专家切片,并在实时 122B 解码的每一步计算一层的专家。输出是正确的。
prompt: "The capital of France is" → 生成结果(手机在环内):" Paris." —— 与本地运行 8/8 token 一致。
实测 · 真实 122B,手机计算 layer-0
正确性 + TPS
8/8
token 与本地一致
4.01
TPS 本地 (基线)
3.13
TPS 手机参与
1.58 GB
自主下载
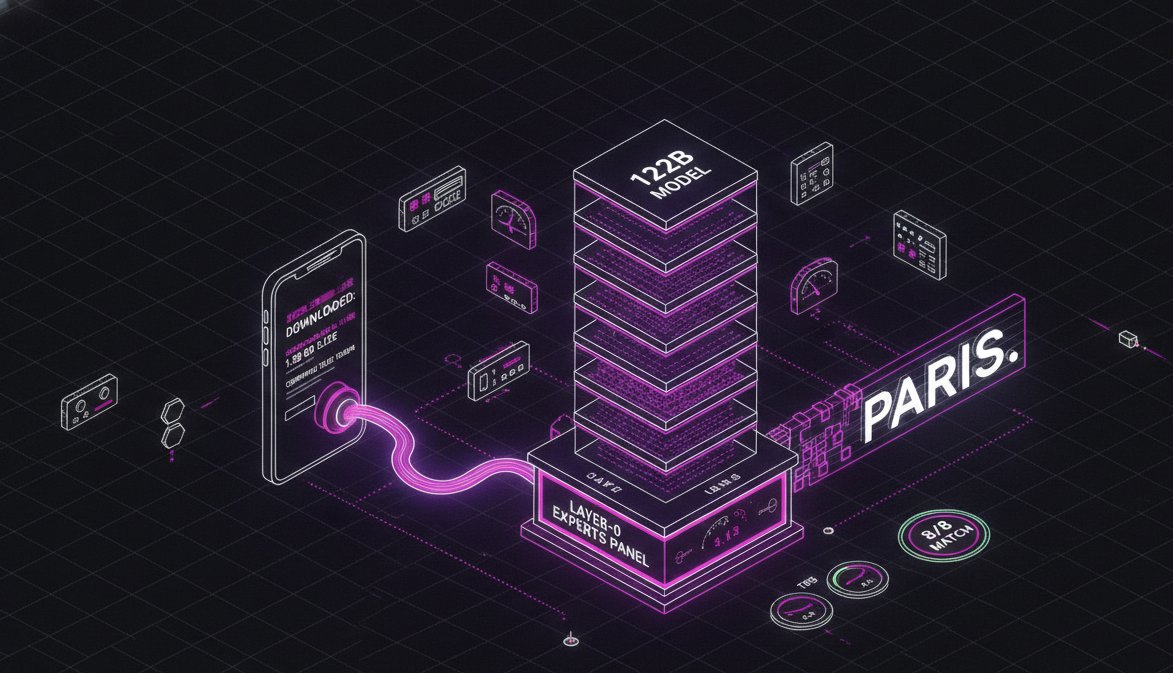
即使手机为每个 token 计算 layer-0 的专家,生成的 token 也与本地完全一致——正确的 "Paris."。TPS 从 4.01 降到 3.13——手机调度往返(MI250 → 隧道 → 手机,每 token 约 100 ms)花掉 22%。吞吐将由批处理与副本找回(M4)。
自治参与流程
发现 → 奖励驱动下载 → 加入计算
1. Phone knows the hub (hub.kvasir-ai.net — retired since; the bridge serves this)
2. GET /api/proxy/models/…/expert-shard?layers=0:1&experts=0:256
   # partially downloads its own expert slice (1.58 GB, WiFi)
3. linkcpp-expert-worker --serve
   # loads the slice (Adreno device, CPU backend) + waits for dispatch
4. MI250 backbone decodes the 122B → every token, layer-0 experts
   dispatch to the phone → experts return → combine → "Paris."
   (8/8 identical to local)
已验证 vs 剩余
机制已完备;应用内循环属于产品化
- 部分下载(expert-shard 端点)、worker 服务、骨干调度、实时 122B 生成与 TPS——全部在真机上验证。
- 正确性:手机参与时 8/8 token 等于本地运行,答案正确。
- 剩余:应用内自治循环(轮询 expert-demand → volunteer → 下载 → serve → 注册)是 Kotlin 接线——本演示直接驱动了机制本身。
- 传输:本演示用了 SSH 隧道;生产使用 443 中继(已在环的工作中验证)。